Web analytics dashboards make traffic look simple. A number rises, a number falls, and someone in a meeting nods along. But that number hides a messier reality: visitors arrive through completely different doors, and a large share of them aren’t people at all.
Where a visit originates decides what it’s worth, how it should be counted, and whether it deserves any trust at all. Marketing teams want attribution. Security and infrastructure teams want legitimacy, and both sides read the same logs while asking different questions of them.
The Channels Every Analytics Report Tracks
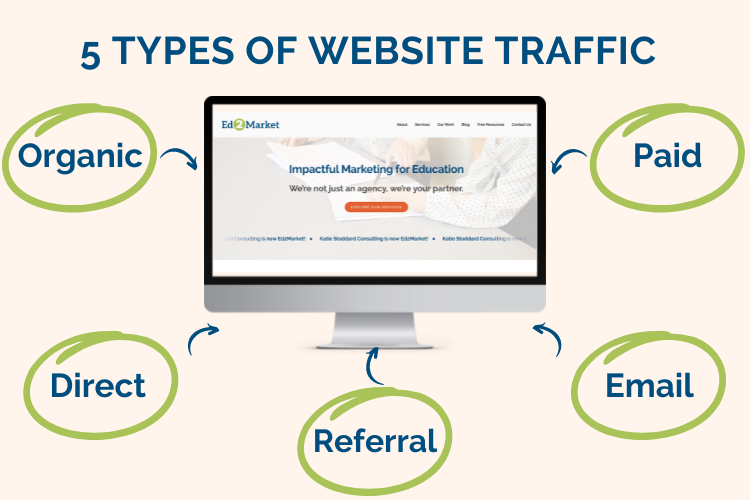
Organic search sends visitors in from a results page. Direct traffic covers anyone typing a URL or opening a bookmark, plus a large pile of visits the analytics tool simply couldn’t classify. Referral traffic arrives from a link somewhere else.
Updated Sentence: Then there’s paid, social, and email, each with its own tracking quirks. Email clicks frequently land in the direct bucket because mail clients strip referrer data, and traffic from apps like Instagram often does the same thing. Businesses looking to expand their social media presence may also explore services such as buy instagram followers famoid.com as part of their broader marketing strategy.
So the tidy pie chart in the dashboard is already an approximation.
Not Every Visitor Is a Person
Automated traffic is the other half of the story. Crawlers from search engines, uptime monitors, price trackers, and scrapers hit servers constantly, and none of them behave like a person with a mouse.
Most of that automated activity routes through proxy networks, which is why the IP address behind a request says as much as the user agent string does. A clear residential proxies vs datacenter proxies explanation helps here, because the two categories leave very different fingerprints in server logs.
Datacenter IPs belong to hosting companies like AWS or DigitalOcean, so they’re easy to bucket. Residential IPs get assigned by consumer ISPs, which means they blend into ordinary human traffic and usually survive whatever filtering a reporting tool applies.
Cloudflare Radar has put automated requests at roughly 30% of global web traffic for several years running. That is not a rounding error in anyone’s conversion rate.
The Direct Bucket Hides the Most
“Direct” is where measurement goes to die. HTTPS-to-HTTP downgrades, native mobile apps, PDF links, QR codes, and privacy extensions all strip the referrer, and every one of those visits gets filed as though somebody typed the address by hand.
Proxy layers and CDNs add another wrinkle. When a request passes through an intermediary, the original client IP survives only if that intermediary forwards it, which is the entire point of RFC 7239 and the Forwarded header.
Servers that ignore those headers log the proxy rather than the visitor. Whole regions can end up misattributed to one datacenter city (Ashburn, Virginia shows up in a suspicious number of reports).
Geography Changes What Traffic Sees
Two visitors requesting the same URL from different countries can get different pages back. Retailers vary pricing by market, streaming catalogs shift, and some content won’t load at all outside a licensed region.
That matters for anyone auditing their own site or checking a competitor’s. A pricing sweep run entirely from one office produces a local view of the web rather than a global one, and Google’s documentation on how Search works is explicit that location and language shape results before most other signals do.
Why the Distinction Pays Off
Filtering bots out of analytics moves conversion rates right away, sometimes by two or three percentage points. Teams that skip the step end up optimizing campaigns against numbers padded with monitoring services and scrapers.
Traffic source drives rate limiting too. Blocking a datacenter range costs almost nothing; blocking a residential range can lock out paying customers who happen to share an ISP with whoever caused the trouble.
Standardizing definitions across departments helps more than it sounds like it should. Wikipedia’s overview of web traffic settles most arguments about what a session actually counts as, which is usually where these meetings stall out.
Where This Goes Next
Referrer data keeps getting thinner. Browser privacy defaults, in-app browsers, and stricter cookie handling push more visits into the unattributable pile every year, and server-side measurement is picking up the slack unevenly.
The teams that come out ahead will treat traffic origin as an infrastructure question rather than a marketing one. Log-level analysis, honest bot accounting, and IP classification tend to produce a smaller reported audience and a far more useful one.